La ingeniería es una disciplina de transformación. Tomamos un estado inicial —muchas veces intuitivo, redundante, caótico o ineficiente— y, mediante principios, metodologías y prácticas de ingeniería, lo transformamos sistemáticamente en un resultado más confiable, optimizado, estructurado y escalable.
En matemáticas, física, ingeniería, informática y otras disciplinas, una transformación representa el proceso mediante el cual un estado, sistema, estructura o representación pasa de una condición a otra siguiendo principios bien definidos.
Transformación es un concepto universal y fundamental del conocimiento científico y técnico, cuyo significado no pertenece ni puede atribuirse al dominio exclusivo de ningun grupo, movimiento, institución, organización, independientemente del uso que pueda hacerse del término en otros contextos.
Este post presenta algunos de los modelos de transformación más representativos utilizados en distintas disciplinas, mostrando cómo condiciones recurrentes son transformadas mediante funciones de transformación basadas en principios, metodologías y prácticas de ingeniería para incorporar nuevas capacidades al sistema.
Este patrón puede generalizarse mediante el siguiente modelo de transformación:
Condición Inicial ➜ Función de Transformación (Engineering Principles, Methods & Practices) ➜ Capacidad Incorporada ➜ Nuevo Estado del Sistema
O expresarse de manera mas simple:
Condición Inicial ➜ Función de Transformación ➜ Capacidad Incorporada ➜ Nuevo Estado del Sistema
Patrones Recurrentes de Transformación en Ingeniería
Los siguientes ejemplos muestran algunos de los modelos de transformación más comunes en distintas ramas.
Aunque son simples de expresar, cada uno representa años —y, en muchos casos, décadas o siglos— de conocimiento previamente desarrollado y materializado en los principios, metodologías y prácticas de cada disciplina.
Mediante la abstracción es posible identificar el modelo general de transformación que subyace a todas estas aplicaciones particulares.
Los ejemplos anteriores constituyen aplicaciones particulares de un mismo modelo general de transformación. En este modelo, una función de transformación permite incorporar nuevas capacidades al sistema, produciendo la transición desde una condición inicial hacia un nuevo estado funcional.
Variabilidad ➜SPC + Statistical Analysis ➜ Predictibilidad➜ Sistema Predecible
Vulnerabilidad ➜Risk Analysis + Fault-Tolerant Design ➜ Resiliencia➜ Sistema Resiliente
Acoplamiento ➜Modularization + Interfaces ➜ Modularidad➜ Sistema Modular
Ineficiencia ➜Lean Thinking + Value Stream Mapping➜Eficiencia Operacional➜ Sistema Eficiente
Configuración Manual ➜Infrastructure as Code ➜ Infraestructura Declarativa➜ Sistema con Infraestructura Declarativa
Ruido ➜Signal Processing + Filtering + Error Correction ➜ Información Confiable➜ Sistema con Información Confiable
Conocimiento Aislado ➜Knowledge Management ➜ Capacidad Organizacional➜ Sistema con Capacidad Organizacional
En este contexto, la ingeniería puede entenderse como una disciplina basada en funciones de transformación que, mediante la incorporación de capacidades al sistema, producen la transición desde un estado inicial hacia estados funcionales mejorados del sistema.
Condición Inicial ➜ Función de Transformación ➜ Capacidad Agregada ➜ Nuevo Estado ➜ Nueva Condición Inicial
Estas capacidades modifican el comportamiento del sistema al permitir controlar, reducir o tolerar condiciones como la variabilidad, la vulnerabilidad, la complejidad, la ineficiencia, el ruido y otras fuentes de incertidumbre que afectan su funcionamiento esperado.
Cuanto mayor es el nivel de incertidumbre presente en un sistema, mayor es la probabilidad de desviaciones respecto a su comportamiento esperado. La incorporación disciplinada de capacidades específicas permite transformar estas condiciones recurrentes, preservando y mejorando la confiabilidad, la adaptabilidad y el desempeño del sistema.
Aplicaciones de las Transformaciones en Ingeniería
Software Engineering
De la Redundancia hacia el Refuerzo
La redundancia deja de ser duplicación innecesaria y se convierte en un mecanismo estructurado para incrementar la resiliencia del sistema frente a fallos.
De la Integración Tardía hacia la Integración y Entrega Continua
Las integraciones esporádicas (“Big Bang”) evolucionan hacia prácticas de integración y entrega continua (CI/CD), incorporando validaciones automatizadas y procesos de entrega más frecuentes, consistentes y controlados.
Big Bang Integration ➜ (CI/CD Pipelines) ➜ Continuous Integration & Continuous Delivery
De la Reacción hacia la Prevención
La corrección reactiva de errores se transforma hacia un diseño preventivo basado en validación temprana.
Del Desarrollo Reactivo hacia el Desarrollo Verificado
La detección tardía de errores evoluciona hacia software verificado mediante validación desde el diseño.
Reactive Development ➜ (Test-Driven Development + Automated Testing) ➜ Verified Software
Production Engineering, DevOps & Infrastructure
De la Respuesta Manual hacia la Recuperación Automatizada
Los procesos manuales de respuesta a incidentes evolucionan mediante la incorporación de automatización, detección y mecanismos de recuperación autónoma, permitiendo que el sistema responda y restaure su operación de manera consistente.
De la Configuración Manual hacia la Infraestructura Declarativa
Las configuraciones manuales evolucionan mediante la incorporación de Infrastructure as Code (IaC), permitiendo definir y gestionar la infraestructura de forma declarativa, reproducible y consistente.
Manual Infrastructure Configuration ➜ (Infrastructure as Code) ➜ Declarative Infrastructure
De los Despliegues Manuales hacia la Entrega Automatizada
Los despliegues manuales evolucionan mediante la incorporación de automatización y prácticas de entrega continua, permitiendo liberar cambios de forma repetible, consistente y confiable.
Del Monitoreo Reactivo hacia la Confiabilidad Proactiva
La operación reactiva evoluciona hacia una gestión de confiabilidad basada en objetivos medibles (SLO ─ Service Level Objectives), que establecen niveles esperados de servicio mediante métricas cuantificables.
El análisis manual de causa raíz evoluciona hacia modelos apoyados por herramientas de diagnóstico que facilitan la recopilación, correlación y análisis de información.
Manual Root Cause Analysis ➜ (AIOps + ML Diagnostics) ➜ Assisted Root Cause Analysis
Del Heroísmo hacia el Trabajo Estandarizado
La resolución de problemas basada en conocimiento individual y experiencia acumulada evoluciona hacia procesos sistemáticos mediante registros técnicos (logging), monitoreo y procedimientos estandarizados. El conocimiento deja de permanecer limitado a individuos específicos y se transforma en una capacidad operacional reproducible.
Heroic Debugging ➜ (Standardized Logging + Monitoring + Runbooks) ➜ Standard Work
Data Engineering
Del Script Ad-hoc hacia el Procesamiento de Datos Orquestado
Los scripts ad-hoc evolucionan mediante la incorporación de pipelines ETL y capacidades de orquestación, permitiendo ejecutar procesos de datos de forma escalable, repetible y confiable.
Del Crecimiento Desordenado hacia la Escalabilidad
El crecimiento no planificado de datos y carga evoluciona mediante la incorporación de patrones de escalabilidad, permitiendo que el sistema mantenga su desempeño y capacidad operativa a medida que aumenta la demanda.
De la Administración Manual de las Bases de Datos hacia la Gestión Operacional Inteligente
Las tareas repetitivas de administración y optimización evolucionan mediante capacidades automatizadas de monitoreo, análisis y optimización que simplifican las actividades operativas y complementan la intervención humana.
Del Registro Caótico hacia la Telemetría Estructurada
Los registros no estructurados evolucionan mediante la incorporación de formatos estandarizados y plataformas de observabilidad, permitiendo generar información operacional consistente, procesable y reutilizable para monitoreo, análisis y automatización.
Ingeniería del Conocimiento: De la Información a la Capacidad Organizacional
Del Conocimiento No Estructurado hacia el Conocimiento Organizado
La información distribuida en documentos, repositorios y otros artefactos de ingeniería se transforma en conocimiento estructurado mediante modelos, esquemas y estándares que permiten su clasificación, descubrimiento, recuperación y reutilización.
Del Conocimiento Individual hacia la Capacidad Organizacional
Las soluciones aisladas desarrolladas por individuos o equipos se convierten en activos de conocimiento reutilizables que fortalecen la capacidad organizacional para resolver problemas de manera consistente y escalable.
Mediante un Knowledge Management Hub, las experiencias, soluciones, decisiones técnicas y prácticas de ingeniería son capturadas, organizadas y transformadas en Knowledge Assets que pueden ser compartidos, reutilizados y mejorados continuamente.
Del Desperdicio del Sistema hacia un Flujo de Valor Optimizado
Mediante principios de Lean Manufacturing, análisis de procesos y mejora continua (Kaizen), se identifican desperdicios como esperas, movimientos innecesarios, retrabajos, sobreproducción o pasos redundantes.
La producción deja de organizarse alrededor de grandes acumulaciones de trabajo y evoluciona hacia un flujo más estable, sincronizado y eficiente.
El objetivo del flujo continuo es que los materiales y productos avancen de manera constante a través del proceso, reduciendo los tiempos de ciclo (cycle time), aumentando la capacidad de respuesta y permitiendo una producción más cercana a la demanda real.
Los inventarios dejan de ser utilizados como una protección contra la incertidumbre y se convierten en un flujo de producción sincronizado con la demanda real.
Inventory Buffer ➜ (Pull System) ➜ Kanban
De la Inspección hacia Poka-Yoke
La calidad no debe depender de detectar errores al final del proceso, sino de diseñar procesos donde los errores sean prevenidos o reducidos significativamente.
La variabilidad deja de ser un comportamiento desconocido del proceso y se convierte en una característica medible, analizable y controlable mediante métodos estadísticos.
Process Variation ➜ (Statistical Process Control – Cp/Cpk) ➜ Process Capability
Electrical & Electronics Engineering
Del Ruido hacia la Optimización de la Señal
Las interferencias se convierten en señales confiables.
A través del procesamiento de señales, métodos de filtrado y técnicas de reducción de ruido, los sistemas separan la información útil de las perturbaciones externas, mejorando la precisión, estabilidad y confiabilidad de las mediciones.
Noise ➜ (Filtering + Error Correction) ➜ Signal Integrity
Del Desajuste de Impedancia hacia la Adaptación
Las pérdidas por incompatibilidad se convierten en transferencia eficiente.
Mediante el diseño de interfaces estandarizadas, protocolos de comunicación y mecanismos de adaptación, los sistemas pueden intercambiar información, energía o recursos de manera más eficiente, reduciendo errores, pérdidas y conversiones innecesarias.
Impedance Mismatch ➜ (Impedance Matching) ➜ Reliable Signal (Signal Integrity)
Generalización Conceptual: Aplicación al Engineering Knowledge Management Framework (ENKMF)
EnK²A→ Engineering Knowledge as a Management Asset
ENKMF→ Engineering Knowledge Management Framework
A partir de la generalización de las funciones de transformación presentadas en este trabajo, es posible formular la siguiente definición:
Definición. (Engineering Capability). Una capacidad de ingeniería es una propiedad funcional u operacional incorporada a un sistema mediante la aplicación sistemática de conocimiento, principios y prácticas de ingeniería, que modifica su estado y amplía sus capacidades para resolver problemas presentes y futuros.
La incorporación de una capacidad constituye una transformación individual. El nuevo estado producido por cada transformación se convierte en la condición inicial de transformaciones posteriores, cuya integración progresiva impulsa la evolución del sistema.
Estas propiedades funcionales u operacionales pertenecen al sistema, no a quienes aplican los principios, prácticas y abstracciones de ingeniería. Su incorporación incrementa la robustez, adaptabilidad, sostenibilidad y calidad del sistema, por lo que constituyen el principal objeto de estudio de las transformaciones presentadas en este trabajo.
Definicion. Confiabilidad del sistema (System Reliability):La confiabilidad de un sistema es la capacidad del sistema para realizar de manera consistente la función para la que fue diseñado, bajo las condiciones de operación previstas. En ingeniería, la confiabilidad constituye una propiedad del sistema y no una percepción subjetiva de confianza.
Esta generalización constituye la base conceptual del framework Towards a Conceptual Framework for Engineering Knowledge Management (ENKMF), en el que el conocimiento generado durante la actividad de ingeniería es progresivamente abstraído, sistematizado, organizado, validado y transformado en capacidades organizacionales reutilizables.
El modelo general de transformación puede representarse de la siguiente manera:
Problem / Initial Condition ➜Engineering Principles, Methods & Practices➜ Engineering Capability ➜ Improved System State
El modelo anterior puede aplicarse directamente al dominio de Engineering Knowledge Management:
En ambos casos, las funciones de transformación incorporan nuevas capacidades de ingeniería y amplían el marco de conocimiento y la capacidad evolutiva de la disciplina.
De las Transformaciones a la Evolución de los Sistemas
Laevolución de un sistemaes el proceso mediante el cual la integración progresiva de capacidades transforma su comportamiento y amplía el conjunto de funciones que el sistema es capaz de realizar. Este proceso continuo de adquisición, integración y refinamiento de capacidades modifica progresivamente las propiedades y el comportamiento global del sistema.
La evolución puede entenderse a partir de dos niveles complementarios de abstracción. (1) El primero describe cómo la ingeniería transforma condiciones recurrentes en nuevas capacidades; (2) el segundo explica cómo la integración progresiva de dichas capacidades impulsa la evolución del sistema.
Del Modelo de Transformación al Modelo de Evolución
Como se presentó anteriormente, el modelo general de transformación describe el mecanismo mediante el cual una condición inicial es convertida, mediante principios, métodos y prácticas de ingeniería, en una nueva capacidad que mejora el estado del sistema.
Problem / Initial Condition ➜Engineering Principles, Methods & Practices➜ Engineering Capability ➜ Improved System State
Sobre esta base puede introducirse un segundo nivel de abstracción: el modelo general de evolución de los sistemas
Modelo General de Evolución de los Sistemas
Mientras que el modelo de transformación explica cómo una condición recurrente se convierte en una nueva capacidad, el modelo de evolución describe cómo la integración progresiva de múltiples capacidades modifica las propiedades y el comportamiento global del sistema.
La incorporación de una capacidad constituye una transformación individual. A medida que un sistema integra múltiples capacidades, estas interactúan entre sí, generando mejoras sucesivas en su estado e impulsando un proceso continuo de evolución.
Engineering Capabilities ➜ Capability Integration ➜ Improved System Properties ➜ System Evolution
Dependiendo de las capacidades incorporadas y de la forma en que estas interactúan, el sistema puede desarrollar propiedades como resiliencia, adaptabilidad, confiabilidad, seguridad, mantenibilidad, escalabilidad, observabilidad o autonomía operacional.
Estas propiedades no sustituyen el papel de la ingeniería ni de la supervisión humana; por el contrario, constituyen el resultado del diseño y de la integración disciplinada de capacidades que incrementan la aptitud del sistema para responder a condiciones de operación cada vez más variables y complejas.
La integración de capacidades constituye, por tanto, un mecanismo general de evolución de los sistemas. Cada capacidad incorporada no solo aporta una nueva funcionalidad, sino que también modifica la forma en que el sistema interactúa con las capacidades previamente existentes, posibilitando comportamientos que no podrían alcanzarse mediante capacidades aisladas.
Caso Particular: Evolución hacia un Sistema Autónomo
La evolución hacia un sistema autónomo constituye una aplicación particular del modelo general de evolución. En este caso, la integración progresiva de capacidades fundamentales incrementa la autonomía operacional del sistema hasta permitir un funcionamiento ampliamente autosuficiente dentro de su dominio de operación.
Fundamental Capabilities (Predictability + Resilience + Modularity + Operational Efficiency + Declarative Infrastructure + Reliable Information + …) ➜ Capability Integration ➜ Operational Autonomy ➜ Autonomous System
Conclusión de las transformaciones en contexto de ingeniería
Aunque las tecnologías, herramientas y terminología difieren entre disciplinas, el proceso fundamental de la ingeniería permanece notablemente consistente. Los problemas recurrentes son transformados sistemáticamente mediante principios, metodologías y prácticas de ingeniería en nuevas capacidades que, con el tiempo, pasan a formar parte del propio marco de conocimiento de la disciplina.
En otras palabras, la ingeniería no consiste únicamente en resolver problemas: consiste en transformar continuamente la complejidad en conocimiento reutilizable, prácticas estandarizadas, sistemas escalables y abstracciones cada vez más poderosas.
Cada transformación incorpora una nueva capacidad; la integración continua de estas capacidades constituye el mecanismo fundamental mediante el cual evolucionan los sistemas de ingeniería. De este modo, se permite que las generaciones futuras construyan sobre los avances alcanzados en lugar de comenzar desde cero.
Este principio refleja una característica fundamental del conocimiento ingenieril: su naturaleza acumulativa y evolutiva. Los nuevos desarrollos rara vez sustituyen por completo los fundamentos existentes; por el contrario, los integran, los refinan, los extienden y construyen nuevas capacidades sobre una base previamente validada.
En consecuencia, la transformación en ingeniería constituye el mecanismo mediante el cual se incorporan nuevas capacidades a los sitemas, mientras que la evolución de los sistemas representa el resultado acumulativo de integrar dichas capacidades a lo largo del tiempo.
Anexo: De las transformaciones en otros contextos
En otros ámbitos, como las ciencias sociales y las políticas públicas, la noción de transformación adquiere un matiz distinto. Aquí, los cambios no siempre siguen un proceso acumulativo y disciplinado como en la ingeniería; más bien, se manifiestan como divergencias ideológicas, reorganizaciones institucionales o redefiniciones culturales que pueden sustituir avances previos sin un método consistente de validación como el que caracteriza a la ingeniería (y/o ciencia).
Esta dinámica implica que las transformaciones sociales y políticas, a diferencia de las ingenieriles, no siempre logran consolidarse sobre fundamentos estables, y en ocasiones reintroducen ideas con consecuencias no previstas o reproducen prácticas con efectos adversos para la sociedad, las instituciones y el medio ambiente.
Mientras que el método científico busca descubrir y explicar fenómenos mediante hipótesis, experimentación y validación objetiva, generando conocimiento acumulativo, las ciencias sociales transforman la realidad a través de interpretaciones, narrativas y marcos normativos que dependen de contextos históricos, culturales y políticos y por lo tanto pueden resultar subjetivos, cambiantes y a veces contradictorios.
Hoy, la ingeniería se distingue por convertir teorías en soluciones operativas (es decir, implementables en la realidad) capaces de sostenerse en entornos dinámicos y complejos. En contraste, las ciencias sociales muestran transformaciones más volátiles, donde la dificultad para aplicar estándares de validación uniforme dificulta verificar un verdadero progreso social… o lo que se debe entender por tal.
Before Java there was C — a language born from the necessity of speaking directly with computer resources. It provided unprecedented control over memory, processes, operating system interfaces, and hardware behavior. Rather than simply expressing instructions, software became the mechanism through which human intention was translated into physical computation.
This power came with a price: C provided minimal abstraction over the underlying machine, leaving many concerns exposed within the system (application) itself. Memory allocation, pointer manipulation, explicit resource management, and system interaction were not hidden behind language or runtime abstractions —they remained fundamental aspects of software design—.
As software systems grew larger, another problem emerged: the machine was no longer the only complexity. The complexity of the problem domain itself became difficult to represent.
As software expanded from controlling machines to representing increasingly complex human systems, a different form of complexity emerged.
Operating systems, databases, embedded platforms, and other infrastructure software continued to benefit from C’s direct relationship with hardware.
However, business applications (systems) faced another challenge: representing entities, relationships, processes, and evolving rules that existed not in the physical machine, but in the conceptual world created by organizations and society. Addressing this new dimension of complexity required programming languages capable of representing increasingly sophisticated conceptual models.
C++: Expanding the Boundaries of Software Abstraction
As software systems became more sophisticated, the challenge was no longer simply controlling the machine, but representing increasingly complex models without sacrificing performance or control. C++ addressed this challenge by extending C with new abstraction mechanisms while preserving its close interaction with the underlying hardware.
Object-oriented programming provided a new way to organize large systems by allowing classes to combine data and behavior into reusable models. Encapsulation, inheritance, polymorphism, templates, operator overloading, and generic programming transformed C++ into a multi-paradigm language capable of expressing highly sophisticated software architectures.
This combination of control and abstraction made C++ one of the most powerful languages in software engineering, enabling everything from operating system components, database engines, compilers, and web browsers to game engines, enterprise transaction processing systems, financial trading platforms, telecommunications infrastructure, embedded devices, robotics, scientific computing, and high-performance distributed systems.
However, this flexibility also introduced a greater number of architectural decisions. C++ enabled the construction of powerful abstractions while preserving direct interaction with the underlying machine. Building robust software required a deep understanding of object lifecycles, manual memory management, stack and heap semantics, constructors, destructors, pointers, references, compilation models, and resource acquisition and release (RAII).
The ability to choose the most appropriate level of abstraction significantly increased expressive power, but it also introduced greater architectural complexity. Design approaches, language features, and resource management strategies had to be carefully balanced to produce software that remained reliable, maintainable, and efficient as systems grew in size and complexity.
C++ provided a richer engineering toolbox, yet the complexity of managing the underlying machine remained an inherent part of software development. The question was no longer whether more power was needed. The question became:
Could increasingly complex software systems continue scaling if responsibilities that could be managed by the platform remained within every software system?
The Idea Behind Java: Moving Complexity Into the Platform
Java emerged in the early 1990s with a different vision. C++ had already demonstrated that complex software systems could be built through powerful language abstractions while preserving direct control over the underlying machine. Java built upon many of those ideas but introduced a different engineering philosophy:
What if responsibilities traditionally managed by the application itself could instead become responsibilities of the runtime?
Java fundamentally changed the relationship between system and the underlying machine.
Instead of every software system directly negotiating with hardware and operating system details, Java introduced a managed execution environment: the Java Virtual Machine (JVM).
The JVM became an abstraction layer between software and physical hardware, relocating responsibilities such as memory management, runtime verification, and platform-specific execution from individual software systems into the runtime itself.
Around the JVM, the Java Runtime Environment (JRE) provided the libraries and components required to execute Java software.
Memory management, portability, security, and architecture-specific execution concerns were no longer handled primarily by the application itself. Instead, these responsibilities were delegated to a managed runtime environment.
Application source code could focus more on expressing solutions.
The runtime would focus more on managing execution.
This simple shift represented a profound change in software engineering. At its core was the Java Virtual Machine (JVM).
The JVM: Hardware Abstraction Through Virtualization
Traditionally, software applications were built for a specific execution environment. Where the source code is compiled directly into architecture-specific machine instructions, making them dependent on a particular processor architecture, operating system, and hardware platform.
Java fundamentally changed this model by introducing an additional layer of abstraction.
Source Code → Bytecode → JVM → Physical Hardware
Instead of compiling applications directly for a physical machine, Java compiles them into platform-independent bytecode executed by the Java Virtual Machine (JVM).
The JVM was not merely a compatibility layer. It became an intelligent execution environment.
It transformed the idea of a programming language from a translator of instructions into a complete computational ecosystem.
The JVM became responsible for:
Garbage collection and automatic memory management.
Bytecode verification and security controls.
Dynamic class loading.
Runtime optimization through Just-In-Time compilation.
Adaptive execution based on system behavior.
Techniques such as method inlining, escape analysis, and speculative optimization allowed the runtime to improve execution dynamically.
The famous promise of Java —“Write Once, Run Anywhere”— was not simply about portability. It represented a deeper transformation:
System stopped being bound directly to the hardware and became dependent on a universal execution environment.
The machine was no longer the final destination.
The runtime became the bridge between human-designed abstractions and physical computation.
Java’s innovation was not merely the introduction of the JVM —it was the relocation of recurring engineering responsibilities into the platform through a higher level of abstraction—.
Java’s Object Model: Controlled Abstraction
Java preserved the essential ideas introduced by object-oriented programming while deliberately removing mechanisms considered too dangerous or complex for large-scale software development. Unlike C++, Java eliminated:
Multiple inheritance of classes.
Pointer arithmetic.
Manual memory deallocation.
Header file dependency management.
The objective was not to reduce capability.
The objective was to reduce unnecessary complexity.
Java embraced the idea that abstraction is not about hiding reality forever; it is about exposing the right level of reality at the right moment.
The Four Foundations of Object-Oriented Design
Encapsulation: Protecting Internal Complexity.
Encapsulation allows objects to protect their internal state and expose controlled behavior.
Through access modifiers such as:
private
protected
public
package-private
Java establishes boundaries between implementation details and external interaction.
An object becomes more than a container of data.
It becomes a controlled unit of responsibility.
Inheritance: Extending Meaning Through Relationships
Inheritance allows new types to extend existing behavior.
Java intentionally supports single class inheritance, avoiding some of the complexity associated with multiple inheritance.
Modern Java continues evolving this concept through sealed classes and interfaces, enabling explicit control over which types may participate in an inheritance hierarchy.
The result is stronger domain modeling and safer reasoning about systems.
Polymorphism: Programming Through Behavior
Polymorphism represents one of the deepest ideas in software engineering:
A system should depend less on what something is and more on what something can do.
Java achieves dynamic polymorphism through runtime method dispatch.
The concrete implementation can change while the abstraction remains stable.
Polymorphism principle became the foundation of frameworks, dependency injection, and modular architectures.
Abstraction: Defining What Matters
Abstract classes and interfaces enable the separation of essential concepts from implementation details.
An abstract class can provide partial behavior.
An interface defines a contract.
Modern Java interfaces evolved beyond simple contracts by adding:
Default methods (Java 8)
Private methods (Java 9)
Sealed interfaces
Java continued expanding abstraction without losing compatibility.
Interfaces: Separating What From How
Interfaces changed software design because they made abstraction explicit. An interface serves as a contract by defining the behavior that software can rely upon while allowing multiple independent implementations to fulfill that specification.
Interfaces introduced a powerful idea: systems should depend on stable contracts (what), not concrete/temporary implementations (how).
A database implementation can change.
A messaging provider can change.
A service implementation can change.
But if the contract remains stable, the architecture remains resilient.
This principle, often expressed as programming to interfaces rather than implementations and formalized by the Dependency Inversion Principle (DIP), became fundamental to enterprise Java, dependency injection frameworks, and distributed systems.
Generics: Reusable Abstractions With Type Safety
Before generics, reusable components often came at the expense of strong compile-time type safety.
Java 5 introduced parameterized types, enabling reusable abstractions while preserving compile-time verification. Collections became safer, APIs became more expressive, and software could model relationships between types with greater precision
Unlike C++ templates, which generate specialized code for each type during compilation, Java generics use type erasure —generic type information exists during compilation to enable type checking but is removed from the generated bytecode— to preserve backward compatibility with earlier versions of the JVM.
This design introduces important language characteristics, including:
Wildcards.
Type bounds.
Bridge methods.
The PECS (Producer Extends, Consumer Super) principle.
PECS is an abstraction because it focuses on how a type is used (producing or consuming data) instead of its concrete implementation, enabling flexible and reusable designs:
Producer: List<? extends T> means the list provides values of type T or its subtypes.
Consumer: List<? super T> means the list accepts values of type T or its supertypes.
Once again, Java followed the same engineering philosophy:
Preserve expressive power while moving complexity into carefully designed language and runtime mechanisms.
Annotations: When Code Began Describing Itself
Annotations introduced another transformation.
Code was no longer only instructions.
Code could also carry information about itself.
Metadata became part of the architecture.
Combined with reflection and dynamic proxies, annotations enabled declarative programming by allowing frameworks to infer behavior from metadata rather than explicit implementation.
Frameworks could discover intentions automatically:
Dependency injection.
ORM mapping.
REST endpoints.
Validation.
Security configuration.
Testing behavior.
The application code described what the system should represent.
The framework determined how that behavior would be implemented.
Java Ecosystem: From Language Features to Reusable Abstractions
Java evolved beyond a programming language and runtime into an ecosystem designed around reusable engineering abstractions. As software systems became more complex, common technical capabilities such as persistence, security, networking, messaging, and web communication moved from individual applications into shared libraries and frameworks. This ecosystem introduced new abstraction layers:
Tools such as Maven extended this model by introducing dependency management through artifacts, coordinates, repositories, and pom.xml configuration. Concepts such as Bill of Materials (BOM) files enabled consistent dependency versions across large systems, allowing applications to consume complex technology stacks as managed building blocks.
Frameworks such as Spring further advanced this approach by providing architectural abstractions for dependency injection, configuration, transactions, web applications, and distributed systems.
Java’s ecosystem transformed software development from building every technical capability from scratch into composing proven abstractions. The responsibility shifted from implementing recurring infrastructure concerns to integrating reusable engineering solutions.
Repeated complexity became reusable platform capability.
Garbage collection represented one of Java’s most important philosophical shifts.
Memory management moved from human responsibility to runtime responsibility.
The JVM became responsible for identifying unused objects and reclaiming resources.
However, abstraction never removes understanding. Modern Java programming still need knowledge of:
Heap structure.
Object allocation.
References.
Memory pressure.
Runtime behavior.
Java did not eliminate the complexity of memory management; it transformed it. The responsibility shifted from manually managing memory blocks to understanding how object lifecycles, allocation patterns, and runtime behavior affect software performance and scalability.
Conclusion: The Transformation of Complexity
Java’s history reflects a fundamental principle of software engineering:
Complexity is never eliminated, it is transformed.
C transformed software development by giving humans direct control over computation.
C++ transformed that control into powerful abstractions.
Java transformed those abstractions into a managed runtime.
The JVM transformed into a platform.
The platform transformed into infrastructure.
Every generation of software engineering has followed the same path:
Humans create abstractions to control complexity.
Then those abstractions become the foundation for the next generation of innovation.
By shifting many recurring sources of complexity into the runtime, Java allowed the platform to enforce guarantees and manage responsibilities that previously remained within application code. In doing so, Java expanded the abstraction boundary beyond the application layer.
Java remains relevant because it continues balancing three forces that define large-scale software engineering:
Abstraction, stability and performance.
A language became a runtime.
A runtime became a platform.
A platform became an ecosystem.
And an ecosystem became one of the foundations of the modern digital world.
Hardware → Operating System → JVM → Java Platform → Frameworks → Application Architecture → Business Domain Solutions
Software evolves through better abstractions.
Each generation of engineering transforms complexity into new foundations upon which the next generation can build.
Large-scale, highly available, and globally distributed software systems that once relied on centralized, dedicated mainframe-based environments can now be implemented on standard server infrastructure (rather than proprietary mainframe hardware), whether deployed on-premises or in the cloud.
Therefore, software engineering is not only about producing code. It is about designing abstractions that allow complexity to be managed across time, teams, platforms, and systems.
By continuously raising the level of abstraction, software engineering has expanded access to large-scale computing, making sophisticated, resilient, and globally distributed systems achievable for organizations of many different sizes.
What if one of history’s greatest philosophical debates about abstraction still shapes how software is designed today?
Nearly three centuries ago, philosopher David Hume challenged the existence of truly abstract ideas. In his book, A Treatise of Human Nature, he argued that the mind never possesses pure abstractions. Instead, what we call general ideas are particular experiences that we reuse through resemblance and habit.
As Hume wrote:
“All general ideas are nothing but particular ones, annex’d to a certain term…”
He illustrated this with a simple example. When we observe a white marble sphere, we perceive its color and shape together. Only after comparing it with other objects —a black sphere or a white cube— do we begin to distinguish color from form.
According to Hume, abstraction is not the perception of an independent idea but the result of comparing experiences and recognizing similarities.
This centuries-old philosophical argument becomes surprisingly relevant when viewed through the lens of software engineering.
Abstraction Beyond Hiding Complexity
Abstraction is often described in SWE books as hiding unnecessary implementation details. While that is certainly part of its purpose, in object-oriented design abstraction serves a broader role: abstraction identifies and models the concepts that best represent a domain.
Good abstraction is not simply about making software easier to use.
Good abstraction is about discovering the concepts that best describe a system, whether those concepts correspond to real-world objects or exist only within the problem domain.
A Customer, a BankAccount, or a Transaction represent tangible entities. However, concepts such as Strategy, Observer, Repository, or MessageBroker are purely conceptual constructs created to model behavior and relationships. Their value lies not in physical existence but in how effectively they represent ideas.
The Four Pillars of Object-Oriented Programming
These ideas are reflected in the classical principles of object-oriented programming:
Abstraction identifies the essential characteristics of a concept while omitting unnecessary details. In languages such as C++, abstract classes with pure virtual functions come closest to representing a “pure concept” because they define behavior without permitting direct instantiation.
Inheritance enables new concepts to extend existing ones while preserving shared behavior.
Polymorphism allows different implementations to satisfy the same conceptual interface.
Encapsulation protects internal state while exposing only the behavior necessary for interaction.
Although often discussed together, these principles solve different problems. Encapsulation controls complexity. Abstraction defines meaning.
Different Languages, Different Approaches
Programming languages provide different mechanisms for expressing abstraction.
C++ emphasizes explicit abstraction through abstract classes, templates, and generic programming, offering exceptional expressive power at the cost of greater complexity.
Java and C# balance abstraction through interfaces, abstract classes, and managed runtime environments, making large-scale system design more approachable.
Python emphasizes behavior over structure, allowing abstractions to emerge from what objects do rather than from where they inherit.
C provides very little language-level abstraction, leaving most conceptual modeling to the programmer.
Each language reflects a different philosophy of how abstraction should be expressed.
From Cognitive Abstraction to Computational Abstraction
According to philosopher David Hume, ideas are connected through three principles of association: resemblance, contiguity, and cause and effect.
Among these, resemblance plays a central role in abstraction, as general ideas emerge by comparing particular experiences and recognizing their similarities rather than from concepts existing independently of experience.
From this perspective, Hume argued that the human mind cannot possess pure abstract ideas independent of particular experiences.
Programming languages, however, provide formal mechanisms for representing abstract concepts through interfaces, abstract classes, and generics.
Whether these constructs constitute true abstract ideas or simply symbolic representations remains an open philosophical question.
Nevertheless, software engineering demonstrates something remarkable: programming languages allow abstract concepts to be expressed explicitly, making it possible to model complex domains through formal representations.
Therefore, programming languages are themselves abstractions —formal systems designed to express other abstractions.
Interfaces, abstract classes, generic types,design patterns, and other software engineering mechanisms are not merelylanguage constructsordevelopment techniques; they provide the means through which abstract ideas can be represented as computational models.
In this recursive hierarchy of abstraction, software systems emerge as layered representations of meaning, enabling increasingly complex domains to be modeled through successive levels of conceptual abstraction.
Based on this reasoning, software engineering does not contradict Hume’s theory of abstraction. Rather, throughprogramming languages, it provides semantic mechanisms for representing the abstractions that originate through the cognitive process described by Hume, allowing them to be formalized as structured computational models.
Questions for Reflection
Does abstraction disappear once complexity is hidden, or does simplification merely create a new layer of abstraction?
Is abstraction fundamentally a cognitive mechanism for understanding reality, with programming languages serving as one of its most formal expressions?
Does the expressive power of a programming language arise from its ability to represent increasingly abstract models of a domain rather than from the number of language features it provides?
If abstraction defines meaning, at what point does an abstraction become so simplified that it no longer preserves the meaning it was designed to represent?
Do programming languages merely represent abstract ideas, or do they enable entirely new forms of abstraction that the human mind alone could never sustain?
Abstraction and Software Development in the AI Era
In the age of AI, the value of software development is shifting from writing code to formalizing ideas.
As AI becomes increasingly fast and capable of generating useful and reusable source code, the core activity is no longer simply implementation —the act of writing code— but identifying the right abstractions, validating AI-generated code, and orchestrating the components that transform those abstractions into complete systems.
Therefore, the future of software development is already emerging: it may no longer be defined solely by writing code, but by thinking more precisely about the ideas that code is meant to represent.
Perhaps abstraction is not simply a programming technique.
It may be one of humanity’s fundamental cognitive tools for understanding, organizing, and engineering reality itself.
Engineering does not advance merely by solving problems; it advances by transforming the knowledge generated through problem resolution into reusable engineering assets that continuously expand organizational capability.
The real engineering problem is not how specific engineering issues, user requests, or incidents are addressed, mitigated, and resolved by particular individuals, but how the engineering knowledge generated throughout the resolution is systematically captured, preserved, refined, propagated, and reused.
From this perspective, an engineering problem is not fully resolved when its immediate objective has been achieved, but when the engineering knowledge generated throughout its resolution has been systematically validated, and incorporated into the organization’s Engineering Knowledge Hub.
This is precisely the objective of the Engineering Knowledge Management Framework: to provide a conceptual model for creating, preserving, transferring, and evolving engineering knowledge throughout its lifecycle, enabling its future discovery, reuse, refinement, and continuous improvement.
Table of Contents
Introduction
Engineering disciplines have evolved independently over decades, each developing their own terminology, methodologies, frameworks, and tools to address the challenges within their respective domains.
Yet, despite these differences, they consistently converge on remarkably similar engineering principles.
Among the activities of engineering, recurring problems are identified, repeatable solutions are discovered, engineering knowledge is generated, practices are refined, standards are established, processes are improved, repetitive tasks are automated, and engineering tools are built to solve problems more efficiently.
At the center of this continuous evolution lies a resource that often receives less attention than software, infrastructure, or technology itself: engineering knowledge.
People join and leave organizations. Software evolves. Technologies change. Organizational structures are reorganized. Products are redesigned. Yet the engineering knowledge accumulated through years of solving real-world problems remains one of the few organizational assets capable of increasing in value when it is deliberately preserved, shared, refined, and reused.
For this reason, engineering knowledge should be regarded as a valuable asset rather than as a collection of isolated documents, tickets, procedures, source code, or individual experience.
The real engineering problem is not how specific engineering issues, user requests, or incidents are addressed, mitigated, and resolved by particular individuals, but how the engineering knowledge generated throughout the resolution is systematically captured, preserved, refined, propagated, and reused.
From this perspective, an engineering problem is not fully resolved when its immediate objective has been achieved, but when the engineering knowledge generated throughout its resolution has been systematically captured, validated, and incorporated into what this framework conceptualizes as the organization’s Engineering Knowledge Hub.
This is precisely the objective of the Engineering Knowledge Management Framework (ENKMF): to provide a conceptual model for creating, preserving, transferring, and evolving engineering knowledge throughout its lifecycle, enabling its future discovery, reuse, refinement, and continuous improvement.
This framework presents the current consolidation of that understanding.
In this context, “that understanding” refers to the concepts, principles, and relationships developed and progressively consolidated within ENKMF itself.
The Engineering Knowledge Paradox
Engineering is often measured by its ability to solve problems.
But every solved problem creates something else: engineering knowledge.
Yet after problems are resolved, the generated knowledge often fades away
If engineering continuously generates knowledge, why doesn’t every recurring problem become progressively easier to understand, diagnose, and resolve?
How can engineering knowledge be captured, preserved, organized, validated, shared, applied, and continuously improved as a reusable engineering asset?
These questions led the author to formulate and develop the Engineering Knowledge Management Framework—a conceptual model that examines how engineering knowledge generated through engineering activities can be transformed into a reusable engineering asset.
Within this context, transient communication refers to information exchanged primarily for immediate coordination, collaboration, or problem resolution. It may include conversations, chat messages, meetings, handovers, emails, and other forms of interpersonal exchange.
Even when such communication is recorded or retained, it remains transient from a knowledge management perspective unless its relevant content is deliberately identified, refined, structured, validated, and made reusable.
Transient communication transfers information between individuals, whereas Engineering Knowledge Management transforms engineering experience into persistent, reusable organizational capability.
Conversations, as one form of transient communication, facilitate collaboration and coordinate people around a particular problem; however, the resulting information represents only an initial input to knowledge management and, unless it is refined, structured, and made reusable, it does not consistently contribute to the organization’s ability to solve similar problems in the future.
Traditionally, production engineering relies either on the accumulated experience of individuals obtained through prolonged exposure to organization-specific systems and environments, or on previous engineering experience combined with the individual ability to rapidly integrate understanding across systems, processes, and business domain contexts to resolve domain-specific, critical, and time-sensitive problems.
In contrast, Engineering Knowledge Management transforms individual knowledge and experience into organizational capability, enabling knowledge to scale beyond individuals and improving problem resolution through faster, more accurate solutions while reducing unintended impacts.
The Engineering Knowledge Management Framework is founded on a simple premise: every engineering activity inherits engineering knowledge from the past and produces engineering knowledge for the future. The engineering outcome solves today’s problem; the engineering knowledge it creates becomes part of the foundation upon which future engineering is built.
The chapters that follow explore the concepts, lifecycle, principles, and mechanisms through which engineering knowledge evolves into long-term engineering capability.
Roadmap
The Engineering Knowledge Management Framework did not emerge as a theoretical model from the outset. It gradually evolved while addressing practical challenges encountered in production engineering and day-to-day engineering operations, together with the broader question of how engineering knowledge generated through those activities could be systematically preserved, refined, and reused.
The initial motivation for these ideas emerged while exploring the design of the ZupportL5 System. The original objective was to improve support engineering by capturing operational experience and making it reusable.
As those ideas matured through continuous reflection and refinement, it became evident that the original software requirements were expressing a broader engineering concept: Engineering Knowledge Management.
The ZupportL5 lema was: “Elevating Support Engineering to the Next Level: L5 — Simplifying Resolutions”
The Engineering Knowledge Management Framework extends this idea through a broader principle: “Engineering Knowledge as a Management Asset“.
A subset of the ZupportL5 user stories that motivated this framework is included in Appendix A — Original Motivation: ZupportL5 User Stories . The current implementation and ongoing evolution of the ZupportL5 System are available in the ZupportL5 GitHub repository, ZupportL5 Documentation.
The chapters in this document are not independent discussions but complementary views of a single Engineering Knowledge Management Framework. Each chapter explores a different dimension of how engineering knowledge is created, transformed, operationalized, and continuously improved.
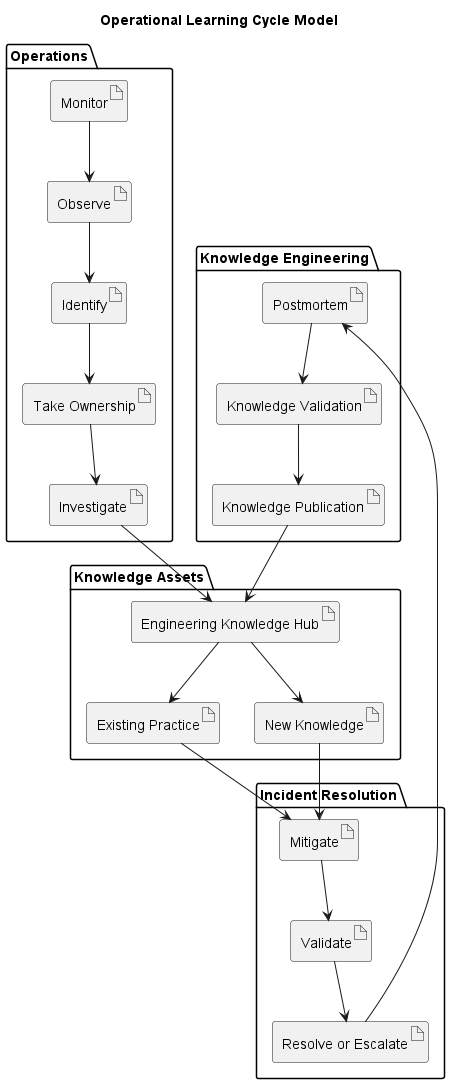
The framework is organized into four complementary layers:
Conceptual Layer — Why engineering knowledge exists and why it should be treated as a strategic engineering asset.
Operational Layer — How engineering activities generate, consume, and refine knowledge through daily operations.
Knowledge Layer — How knowledge is captured, validated, managed, and continuously evolved.
System Layer — How the Engineering Knowledge Management Framework can be operationalized through an Engineering Knowledge Hub that integrates engineering knowledge, engineering artifacts, automation, and AI-assisted capabilities. ZupportL5 represents one possible implementation of this layer.
Together, these layers describe a continuous engineering framework in which engineering activities generate organizational knowledge, organizational knowledge becomes engineering practice, and engineering practice becomes organizational capability
For the purposes of this document, an Engineering Knowledge Management Framework is defined as a structured model that integrates engineering principles, operational processes, knowledge management practices, and platform capabilities into a unified approach for creating, preserving, and continuously improving engineering knowledge.
Two conceptual identifiers are used throughout this work to represent its central principle and the framework developed around it:
EnK²A → Engineering Knowledge as a Management Asset
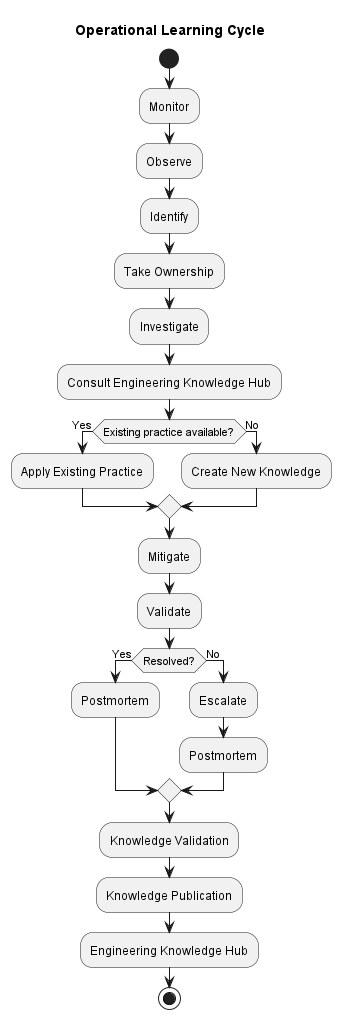
Engineering continuously addresses production incidents, software defects, infrastructure failures, deployment issues, domain-specific user requests, operational tasks, and both new and previously encountered engineering problems.
From an operational perspective, the objective is clear:
Assess the impact.
Mitigate the issue.
Restore normal operation.
Close the ticket
However, from an engineering perspective, resolving the incident is only part of the process.
Every investigation produces engineering knowledge:
Root causes
Observations
Workarounds
Better procedures
Design improvements
Operational experience
Without preserving that knowledge, previous experience cannot be systematically reused.
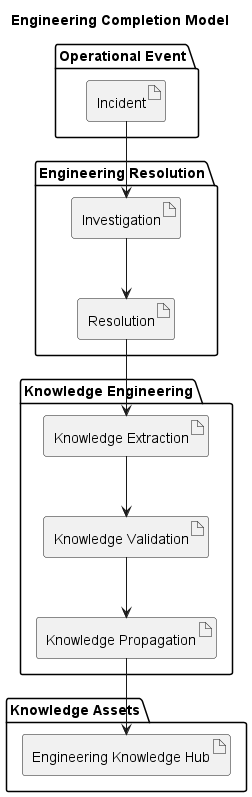
When an engineering activity generates reusable knowledge, engineering completion extends beyond closing the immediate issue to validating, propagating, and incorporating that knowledge into the organization’s Engineering Knowledge Hub.
Operational vs. Engineering Completion
Operational Completion:
Engineering Completion:
Fundamental Questions
If an engineering problem is not truly resolved until the knowledge generated throughout its resolution becomes part of the organization’s engineering capability, fundamental questions arise:
What constitutes engineering knowledge?
Why is engineering knowledge frequently lost despite being continuously generated?
How is engineering knowledge created through engineering activities?
How can engineering knowledge be systematically created, captured, preserved, validated, transferred, organized, shared, applied, and continuously improved?
How does engineering knowledge evolve throughout its lifecycle?
How do engineering practices emerge from engineering knowledge?
How do engineering artifacts preserve, communicate, and operationalize engineering knowledge?
How does engineering knowledge become organizational engineering capability?
How can engineering knowledge reduce future engineering effort while improving reliability, consistency, and scalability?
How does the continuous evolution of engineering knowledge enable continuous improvement?
The Engineering Knowledge Management Framework presented in this work seeks to provide a conceptual model that integrates the principles, practices, artifacts, and processes involved in answering these questions and managing engineering knowledge throughout its lifecycle.
Throughout this work, operationalized refers to the process by which engineering knowledge is transformed from documented or implicit knowledge into an integral part of engineering activities.
Once operationalized, knowledge no longer exists only as information—it actively guides decisions, defines processes, supports execution, and can ultimately be standardized and automated.
I.2. Engineering Knowledge as a Valuable Asset
Why Is Knowledge an Asset?
Organizations invest heavily in infrastructure, software, automation, human resources, and technology.
Yet one of their most valuable assets is generated continuously as a consequence of engineering itself:
Engineering Knowledge.
Unlike physical assets, engineering knowledge does not diminish through use. Every time it is reused, refined, validated, and shared, its value expands—extending its applicability, increasing its coverage, strengthening its reliability, and enriching the collective engineering capabilities of the organization.
Technology changes.
Products evolve.
People change roles.
Organizations reorganize.
Engineering knowledge remains the mechanism that allows organizations to continuously improve, and ultimately to operate with resilience, coherence, purpose, and sustainability.
Engineering knowledge should therefore be regarded as a valuable organizational asset rather than as isolated documentation distributed across tickets, source code, chat conversations, procedures, or individual experience.
Evolution of Organizational Knowledge
Knowledge only becomes an organizational asset when it can be discovered, understood, reused, and continuously improved.
I.3. Engineering Practices
What Is an Engineering Practice?
Engineering progresses by solving recurring problems.
Over time, successful solutions are repeated, refined, validated, and eventually recognized as better ways of working.
These become Engineering Practices.
Engineering practices represent the collective knowledge accumulated through the contributions of countless individuals who, through repeated observation, refinement, and validation, discovered more effective ways to solve problems. Over time, these approaches become documented as Engineering Practices and eventually evolve into Standards.
Engineering practices are not software tools.
Engineering practices are not documents.
Engineering practices are not automation.
They are abstractions of validated engineering knowledge.
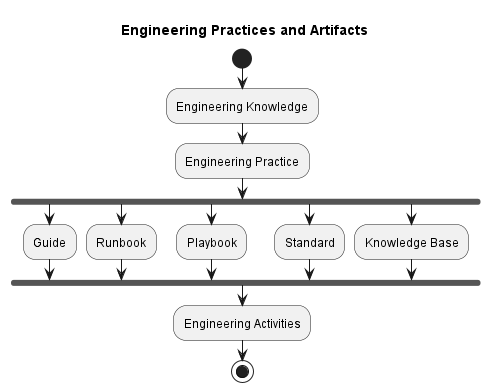
Documentation communicates practices.
Standards institutionalize practices.
Automation executes practices.
Engineering tools automate practices.
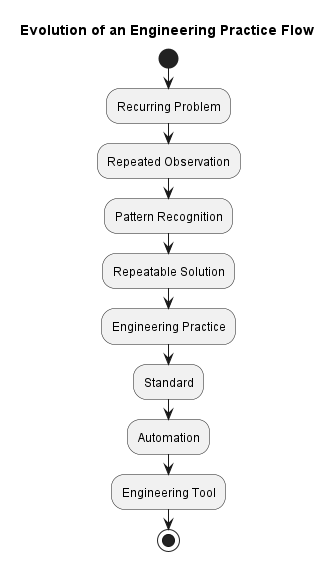
Evolution of an Engineering Practice
This evolution explains why engineering continuously advances.
Every successful engineering abstraction enables future engineering to solve problems more consistently, efficiently, and at greater scale.
Part II — Engineering Knowledge Foundations
II.1. Engineering Knowledge Taxonomy
How Is Engineering Knowledge Classified?
Engineering knowledge may exist in tacit, codified, or embedded forms. Not all valuable engineering knowledge can or should be transformed into documentation. Engineering Knowledge Management therefore seeks to make knowledge discoverable, transferable, applicable, and reusable through appropriate mechanisms: artifacts when knowledge can be codified, collaborative practices when knowledge remains substantially tacit, and engineering processes, systems, and tools when knowledge becomes embedded.
Engineering practices are abstract. They define how recurring engineering problems are solved but do not, by themselves, provide a tangible means for communicating or preserving that knowledge.
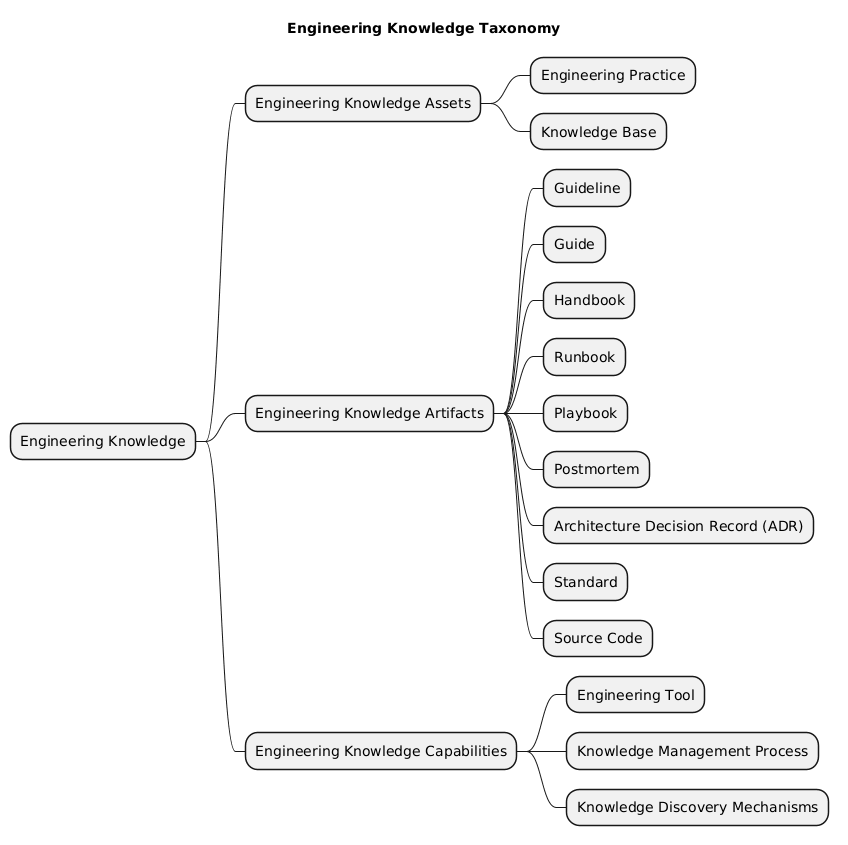
To establish a common vocabulary, this framework distinguishes three complementary dimensions of Engineering Knowledge Management: engineering knowledge assets, engineering knowledge artifacts, and engineering knowledge capabilities. Together, these dimensions describe the organizational value of engineering knowledge, how it is represented, and how it is created, managed, and applied throughout its lifecycle
Engineering Knowledge Assets
Engineering knowledge assets are reusable bodies of engineering knowledge that possess enduring organizational value. They represent the knowledge an organization intentionally preserves because it contributes to its engineering capability over time.
Definition
Engineering Knowledge Asset: A reusable body of engineering knowledge that contributes to an organization’s capability to design, build, operate, maintain, or improve engineering systems.
Engineering Knowledge Asset
Purpose
Engineering Practice
Defines how recurring engineering problems are solved.
Knowledge Base
Preserves and organizes reusable engineering knowledge for discovery and reuse.
Engineering Knowledge Artifacts
Engineering knowledge assets become reusable through artifacts, which transform abstract engineering knowledge into tangible representations that can be consistently shared, reviewed, versioned, maintained, and applied across engineering teams. By decoupling knowledge from its original contributors, artifacts enable engineering knowledge to persist, evolve, and remain accessible throughout the engineering lifecycle..
Definition
Engineering Knowledge Artifact: A tangible representation of engineering knowledge created to document, communicate, preserve, govern, or implement engineering knowledge.
Artifact
Purpose
Guideline
Recommends preferred approaches.
Guide
Explains concepts and procedures.
Handbook
Organizes engineering knowledge within a domain.
Runbook
Provides executable operational procedures.
Playbook
Coordinates responses across multiple scenarios or teams.
Postmortem
Captures lessons learned after significant events.
Although these artifacts differ in purpose, they all represent different forms of engineering knowledge.
Engineering Knowledge Capabilities
Engineering knowledge capabilities are the organizational mechanisms that enable engineering knowledge to be created, managed, validated, applied, automated, and continuously improved. They transform engineering knowledge into organizational capability.
Definition
Engineering Knowledge Capability: An organizational capability that enables the creation, management, application, automation, or continuous improvement of engineering knowledge.
Engineering Knowledge Capability
Purpose
Engineering Tool
Automates or supports engineering practices and workflows.
Knowledge Management Process
Governs the lifecycle of engineering knowledge from creation through continuous improvement.
Knowledge Discovery Mechanisms
Identify, extract, validate, and transform engineering knowledge into reusable organizational assets.
Relationship Between the Categories
Engineering practices define how recurring engineering problems are solved. Engineering artifacts embody and communicate those practices, while engineering capabilities enable their application, governance, automation, and continuous improvement.
Together, these categories provide a comprehensive classification of engineering knowledge by distinguishing its organizational value (assets), representation (artifacts), and enablement (capabilities).
Engineering knowledge assets define what possesses enduring organizational value.
Engineering knowledge artifacts define how engineering knowledge is represented, documented, communicated, preserved, and implemented.
Engineering knowledge capabilities define how engineering knowledge is created, managed, applied, automated, and continuously evolved.
Together, they establish the conceptual foundation of the Engineering Knowledge Management Framework and provide a consistent taxonomy for describing engineering knowledge throughout its lifecycle.
II.2. Engineering Knowledge Management Lifecycle
How Does Engineering Knowledge Evolve? (Knowledge Lifecycle)
Engineering knowledge is continuously generated throughout engineering activities.
Without a structured lifecycle, valuable knowledge becomes fragmented across systems, documents, tickets, conversations, and individual experience.
Engineering Knowledge Management provides the process through which engineering knowledge is continuously improved.
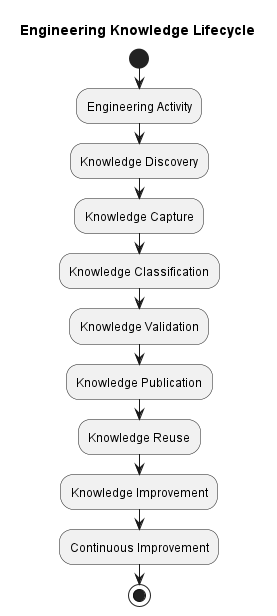
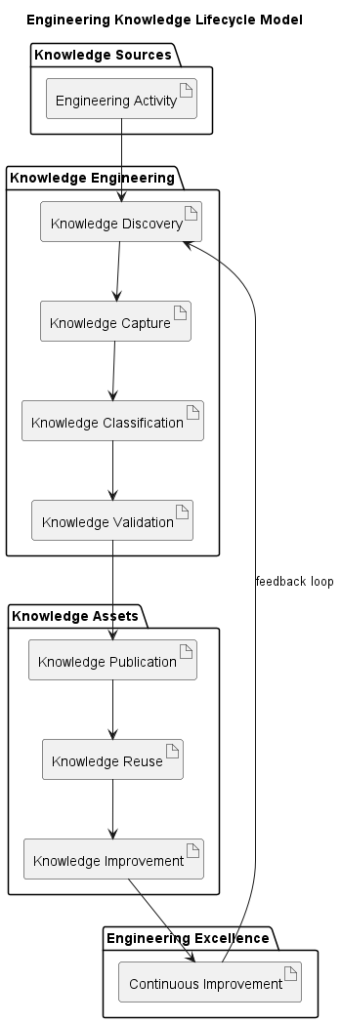
Engineering Knowledge Lifecycle
Each phase of the Engineering Knowledge Management Lifecycle transforms engineering experience into increasingly reusable organizational capability.
Together, these phases establish a continuous process in which knowledge is systematically identified, structured, validated, shared, applied, and refined, ensuring that engineering experience extends beyond individual activities and contributes to the organization’s long-term engineering capability.
Phase
Description
Input
Output
Engineering Activity
Engineering work generates experience through design, implementation, operation, maintenance, troubleshooting, or analysis.
Engineering work
Engineering experience
Knowledge Discovery
Identify engineering experience that has long-term organizational value.
Engineering experience
Identified knowledge
Knowledge Capture
Transform engineering experience into explicit and reusable knowledge artifacts.
Identified knowledge
Knowledge artifacts
Knowledge Classification
Organize knowledge using categories, metadata, relationships, and domains.
Knowledge artifacts
Structured knowledge
Knowledge Validation
Verify that knowledge is technically correct, complete, consistent, and reusable.
Structured knowledge
Validated knowledge
Knowledge Publication
Make validated knowledge accessible through organizational knowledge repositories.
Validated knowledge
Published knowledge
Knowledge Reuse
Apply published knowledge to solve engineering problems more efficiently and consistently.
Published knowledge
Improved engineering outcomes
Knowledge Improvement & Lifecycle Maintenance
Refine, update, supersede, archive, or retire knowledge using new engineering experience, lessons learned, technological evolution, and evolving engineering practices.
Reused knowledge and new experience
Improved knowledge
Each engineering activity contributes to the Engineering Knowledge Hub.
Likewise, each future engineering activity benefits from the accumulated knowledge already preserved within the hub.
The lifecycle therefore forms a continuous feedback process rather than a one-time documentation effort.
II.3. Engineering Knowledge Responsibility Model
Engineering knowledge does not emerge from a single role or activity; it is the result of coordinated contributions across different support domains. Each role contributes according to its proximity to the problem, domain expertise, and responsibility within the engineering lifecycle.
Defining these responsibilities ensures that valuable experience is not only captured but transformed, validated, maintained, and evolved as organizational capability.
The following paragraphs define the knowledge contribution responsibilities of each role according to the proposed Engineering Knowledge Framework.
Business Users, Data Stewards and Business Domain Experts
Business domain users represent the source of business knowledge required for understanding processes, operational objectives, data meaning, and expected system behavior.
Within the Engineering Knowledge Framework, they should contribute domain knowledge by providing:
Business process context
Functional requirements
Data definitions and interpretation rules
Expected application behavior
Business impact assessment
Validation of functional solutions
Their role is not to manage technical solutions, but to provide the business knowledge required for engineering teams to correctly analyze, design, and validate system changes.
Framework Contribution: Generate and validate business knowledge assets that provide context for incidents, system behavior, data interpretation, and application evolution.
Engineering Support / Production Engineering / Site Reliability Teams
Engineering Support represents the operational engineering function responsible for maintaining service reliability and transforming operational experience into reusable engineering knowledge.
Within the Engineering Knowledge Framework, they should capture and formalize knowledge generated during:
Incident investigation
Service request resolution
Troubleshooting activities
Root cause analysis
System behavior analysis
Operational improvements
Their contribution should include the creation and maintenance of:
Troubleshooting guides
Runbooks
Operational procedures
Known issue documentation
Incident knowledge records
Root cause analysis documentation
When issues require application-level changes, Engineering Support should provide Application Development teams with technically enriched information, including investigation results, evidence, impact analysis, and identified causes.
Framework Contribution: Transform operational problem-solving experiences into engineering knowledge assets that improve reliability, reduce repeated effort, and enable knowledge reuse.
Application Development / Application Engineering Teams
Application Development owns the software systems, including source code and product functionality.
Within the Engineering Knowledge Framework, they should contribute knowledge generated from:
Code changes
Defect resolution
Application enhancements
Product Feature Requests
Database modifications
Design decisions
Release activities
Their knowledge contributions should include:
Technical documentation
Design decisions
Release information
Change impact documentation
Application behavior updates
Application Development should also review and enrich knowledge captured from production issues when system changes are required.
Framework Contribution: Transform software evolution activities into technical knowledge assets that preserve system understanding and support future engineering activities.
Engineering Knowledge Governance
Knowledge Governance defines the structure, standards, and lifecycle required to maintain engineering knowledge as an organizational capability.
Within the framework, governance should establish:
Knowledge classification models
Ownership responsibilities
Validation processes
Review cycles
Publication standards
The governance function ensures that knowledge generated from business operations, production support, and software development activities becomes structured, accessible, and continuously improved.
Framework Contribution: Enable the transformation of individual experience and project-specific information into sustainable organizational engineering knowledge.
Therefore, engineering knowledge is generated through engineering activities, transformed through engineering understanding, and sustained through engineering ownership.
Effective knowledge management depends not only on preserving information, but on continuously transforming engineering experience into reusable organizational capability
II.4. Continuous Improvement Through Engineering
Why Does Engineering Continuously Evolve? (Closed-Loop & Recursive Evolution)
Engineering continuously evolves.
Every solved problem contributes to future engineering capability.
As repeatable solutions emerge, they become engineering practices.
Once practices have demonstrated consistency, they become suitable candidates for automation.
Automation enables engineering to address larger systems, higher volumes, and increasingly complex challenges.
Those new capabilities inevitably introduce new engineering problems.
The cycle then repeats.
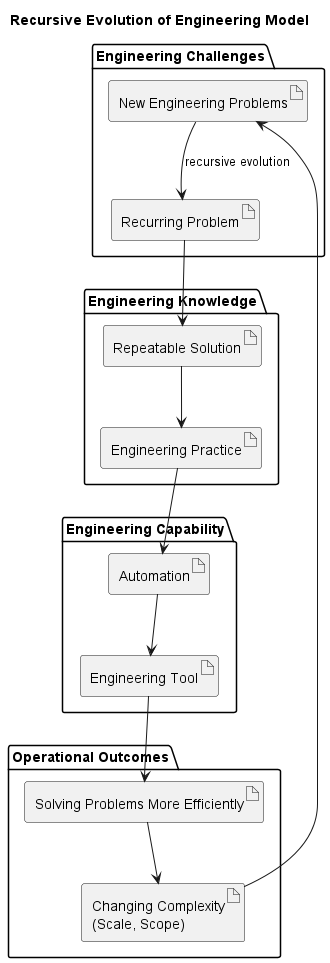
Recursive Evolution of Engineering
Software engineering is recursive in the sense that it evolves through a closed-loop continuous improvement process.
Engineering solves problems.
Repeatable solutions become engineering practices.
Engineering practices can be automated.
The resulting software becomes the next generation of engineering tools, enabling engineering to solve increasingly complex problems.
Every successful engineering abstraction expands the frontier of what engineering can address.
That expanded frontier inevitably creates the next generation of engineering problems.
Engineering evolution is recursive: every capability developed to solve existing problems transforms the operational environment, creating new challenges that drive the next generation of engineering knowledge and capability.
Part III — Generalization of the Framework
III.1 Universal Engineering Lifecycle
How can the Engineering Knowledge Management Framework be applied across different engineering disciplines?
Although the engineering inputs differ across disciplines, the lifecycle of engineering knowledge remains fundamentally the same.
Whether the work begins with a software requirement, an operational incident, a system integration issue, a network change, or a security vulnerability, the engineering objective extends beyond achieving the immediate operational result.
It also includes transforming the knowledge generated during that work into a reusable organizational asset that strengthens future engineering capabilities.
This observation suggests that the Engineering Knowledge Management Framework is not limited to Operations or Site Reliability Engineering.
Rather, it describes a general engineering principle that can be applied across multiple engineering disciplines.
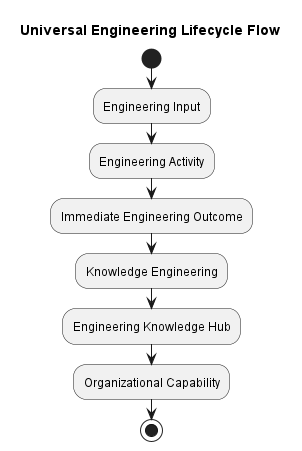
The common engineering lifecycle can be summarized as follows:
The nature of the engineering input varies according to the discipline, while the remainder of the lifecycle remains essentially unchanged.
Engineering Discipline
Typical Engineering Input
Software Engineering
Requirements, user stories, design specifications
Systems Engineering
Change requests, system requirements, integration issues
User requests, support tickets, product defects, customer-reported issues
Site Reliability Engineering
Incidents, alerts, operational events, service degradations
From this perspective, Engineering Knowledge Management is not limited to an operational function; within engineering organizations, it acts as a cross-cutting capability spanning multiple engineering disciplines.
The source of the work may differ, but the lifecycle through which engineering knowledge is created, validated, preserved, shared, and reused remains fundamentally the same.
This perspective also clarifies the role of the Engineering Knowledge Hub. It should not be viewed as an incident management repository or a documentation platform, but as the organizational mechanism through which engineering knowledge from diverse disciplines is integrated, preserved, and transformed into reusable organizational capability.
Ultimately, this framework shifts the engineering perspective from asking “How do we solve engineering problems?” to asking “When is an engineering problem truly solved?”
Within this framework, an engineering problem is considered fully resolved only when the knowledge generated during its resolution has been integrated into the Engineering Knowledge Hub, where it becomes discoverable, reusable, and capable of contributing to future engineering activities and continuous organizational improvement.
Regardless of the engineering discipline or the origin of the engineering work, the abstract lifecycle through which engineering knowledge is created, validated, preserved, shared, and reused remains fundamentally consistent across engineering disciplines, while engineering inputs, artifacts, validation criteria, governance constraints, and implementation mechanisms vary according to the domain.
III.2 Engineering Knowledge Across Domains
The transformation of engineering experience into organizational capability is not exclusive to software engineering. Across engineering disciplines, execution activities generate observations, deviations, failures, and improvement opportunities that must be captured, analyzed, and transformed into reusable knowledge.
Manufacturing disciplines have long applied this principle through mechanisms such as test findings, defect reports, non-conformance records, corrective actions, and lessons learned. These practices demonstrate a fundamental engineering pattern:
Production Execution → Abnormality Detection → Problem Identification → Root Cause Analysis → Knowledge Capture → Kaizen Improvement (continuous improvement) → Operational Excellence (OpEx)
Electrical engineering has long applied structured approaches for transforming operational experience into engineering improvement. Through established practices such as fault analysis, failure analysis, reliability engineering, and maintenance management, electrical systems use failure events as sources of knowledge that drive corrective actions, design improvements, and increased reliability:
Software engineering can apply the same underlying engineering principle by extending operational problem resolution into knowledge creation and capability improvement, as described in this framework:
Production Operation → Incident Identification → Investigation → Root Cause Analysis (RCA) → Knowledge Artifact → System and Practice Improvement → Organizational Capability
Although the artifacts and terminology vary across disciplines, the underlying knowledge evolution process remains consistent. As established in this framework, Engineering Knowledge Management provides a conceptual model for understanding and enabling this process regardless of the domain, technology, or implementation approach.
Part IV — Engineering Knowledge Hub
IV.1. From Operational Events to Organizational Knowledge
How Do Operations Feed That Cycle?
Every engineering activity produces knowledge.
Incidents, changes, deployments, maintenance tasks, investigations, and postmortems all contribute to the continuous evolution of engineering knowledge.
The objective is not only to restore normal operation, but to improve future engineering capability.
Operational events therefore become opportunities to enrich the Engineering Knowledge Hub.
Operational Learning Cycle — An Application of the Engineering Knowledge Management Framework
Knowledge should not remain exclusively inside tickets.
While tickets can serve as valuable sources of operational knowledge through detailed analysis, resolution steps, and contextual comments that support future similar cases, this knowledge should be transformed into reusable engineering capability.
Every completed engineering activity should leave the organization better prepared for the next one.
Every operational activity is a consumer and a potential producer of engineering knowledge. The Engineering Knowledge Hub is therefore not merely a repository, but the central mechanism through which organizational learning is continuously accumulated, validated, and reused.
IV.2. The ZupportL5 Vision
How Can This Vision Be Implemented? (ZupportL5)
The initial motivation behind the ZupportL5 System was to improve support engineering by making operational experience reusable.
As the concept matured, it became evident that the underlying challenge was broader than ticket management.
The vision evolved toward an Engineering Knowledge Hub capable of supporting the complete Engineering Knowledge Management lifecycle.
Rather than replacing existing enterprise platforms, ZupportL5 complements them by connecting engineering knowledge across operational activities.
Its objective is to guide engineering knowledge through its complete lifecycle, from discovery to continuous improvement.
Potential capabilities include:
Knowledge discovery
Knowledge correlation
Knowledge validation
Knowledge standardization
AI-assisted knowledge retrieval
AI-assisted knowledge generation
Knowledge lifecycle management
Continuous improvement support
Conceptual Integration
The Engineering Knowledge Hub does not replace engineering judgment or experience; it strengthens engineering capability by making organizational knowledge reusable, accessible, easier to apply, and more reliable.
It amplifies engineering by preserving, organizing, and continuously improving engineering knowledge.
Conclusions
Engineering Knowledge Management provides a unified perspective in which every engineering activity simultaneously consumes existing knowledge and contributes to the continuous development of new organizational knowledge.
From this perspective, engineering knowledge is not a by-product of engineering work but one of its primary assets.
Thus, engineering organizations create value not only by solving immediate problems, but by continuously strengthening the ability to solve future engineering problems through the systematic management of engineering knowledge.
This perspective extends the traditional approaches to knowledge transfer, such as on-call handovers, transition meetings, or knowledge transfer (KT) sessions.
While these engineering practices remain valuable, they represent activities within the broader Engineering Knowledge Management cycle rather than the primary mechanism by which engineering knowledge is created, captured, preserved, organized, validated, transferred, applied, and continuously improved.
Engineering knowledge should not depend on the availability, memory, personal interpretation, or goodwill of particular individuals. Instead, it should continuously evolve through the Engineering Knowledge Management cycle, transforming experience into organizational engineering knowledge.
This principle is consistent with established engineering practices. Well-engineered artifacts should communicate the engineering knowledge they embody with sufficient clarity to be understood, applied, maintained, and improved by other individuals with minimal reliance on the original contributors.
Therefore, engineering knowledge should remain highly cohesive with the engineering artifacts it describes while remaining loosely coupled from specific repositories, individuals, or tools.
In software development, through appropriate design, structure, naming, and documentation where necessary, the code itself becomes a representation of engineering knowledge.
The same principle applies equally to architecture guidelines, operational procedures, runbooks, automation, standards, technical documentation, engineering models, and every other engineering artifact.
Work that remains isolated to a single engineering activity delivers value only once, whereas work that contributes to the Engineering Knowledge Management cycle extends its value beyond the immediate solution.
As organizational engineering knowledge accumulates, each engineering activity contributes to increasing the organization’s long-term engineering capability, enabling future engineering work to be performed more effectively, efficiently, consistently, and at greater scale.
The framework presented throughout this work can be summarized by the following principles:
Engineering knowledge is one of the most valuable assets generated through engineering activities.
Engineering practices represent validated approaches for solving recurring engineering problems.
Engineering artifacts preserve, communicate, operationalize, govern, and support the automation of engineering knowledge.
Lifecycle consistency remains the same across disciplines; only the engineering inputs differ.
Problems resolved are fully resolved only when the knowledge generated is integrated into the Engineering Knowledge Hub.
Knowledge Hub provides the organizational foundation for preserving, integrating, and continuously improving engineering knowledge across disciplines.
Continuous improvement depends on the continuous improvement of engineering knowledge.
Automation is a natural progression for mature, repeatable engineering practices when automation is technically and organizationally appropriate.
Abstractions expand the frontier of engineering and create the next generation of engineering problems.
ZupportL5 represents one possible implementation of the Engineering Knowledge Management Framework, demonstrating how these principles can be operationalized through an integrated Engineering Knowledge Hub.
Reflective Questions
When consistently applied, this framework should provide guidance for answering questions such as the following:
How much engineering knowledge was created, captured, preserved, validated, transferred, applied, or improved?
How effectively was individual engineering knowledge transformed into organizational engineering knowledge?
How broadly can the resulting engineering knowledge be applied across similar problems, systems, disciplines, or domains?
How easily can another engineer understand, apply, maintain, extend, and improve the resulting engineering knowledge?
How many future engineering problems could be prevented through the application of this knowledge?
To what extent did it reduce future engineering effort, complexity, or resolution time?
To what extent did it increase the organization’s engineering capability?
To what extent did it reduce dependency on individual expertise?
How effectively did it improve the organization’s ability to solve future engineering problems?
While the Fundamental Questions seek to understand the nature, origin, and evolution of engineering knowledge, the Reflective Questions encourage continual examination of how that knowledge is applied to strengthen organizational engineering capability. Together, they distinguish conceptual understanding from practical evaluation, establishing a foundation for continuous improvement and long-term effectiveness.
These questions are not meant to impose a universal model of measurement; rather, they serve to illustrate the vantage point established by this framework.
From this perspective, valuable insights emerge ─guiding the refinement of engineering methods, the strengthening of standards, the design of more reliable systems, and the creation of sustainable solutions that can adapt and endure alongside future engineering needs.
Future Work
Future work may further refine and extend the Engineering Knowledge Management Framework by:
Formalizing the classification of engineering artifacts, practices, and knowledge assets
Refining the Engineering Knowledge Management lifecycle and its underlying principles.
Defining the conceptual relationships among engineering activities, knowledge, practices, standards, automation, and organizational capabilities.
Developing conceptual, logical, and physical models for the Engineering Knowledge Hub.
Applying the framework across additional engineering disciplines to further validate its generality and applicability.
Implementing these concepts through the ZupportL5 system while continuously refining the framework through practical engineering experience and operational insights.
Developing AI-assisted capabilities within ZupportL5 to support the discovery, validation, organization, and continuous improvement of engineering knowledg
Appendix A — Original Motivation: ZupportL5 User Stories
The Engineering Knowledge Management framework presented in this article emerged while exploring the design of the ZupportL5 System.
Initially, the objective was to improve support engineering through the systematic consolidation of operational knowledge enhancing engineering problem resolution. Over time, this practical objective naturally evolved into the framework presented in this work.
The following user stories represent a subset of the original requirements that ultimately motivated the development of the Engineering Knowledge Management Framework presented in this work.
Knowledge Preservation
As a Support Engineer, I want to access a centralized knowledge base so that I can quickly find relevant information to resolve issues.
Knowledge Operationalization
As a Support Engineer, I want workflow automation to execute runbooks that guide engineering best practices so that I can resolve issues efficiently and consistently.
Knowledge Transfer
As an On-call Engineer, I want a streamlined handover process so that I can transfer the current status of ongoing engineering activities without loss of operational knowledge or context.
Knowledge Discovery
As a Support Engineer, I want to quickly access historical information about similar engineering activities so that I can reuse previous knowledge and accelerate problem resolution.
AI-Assisted Knowledge Discovery
As a Support Engineer, I want a diagnostic capability that provides AI-assisted knowledge discovery so that I can identify potential solutions and root causes more efficiently.
Knowledge Integration
As a System Engineer, I want to integrate engineering knowledge with monitoring systems so that operational events contribute to the continuous Engineering Knowledge Management lifecycle.
Although originally defined as software requirements, these user stories reveal the core capabilities required by an Engineering Knowledge Management system. They illustrate the practical motivation that eventually evolved into the conceptual framework presented in this work.
Methodological Reflection
This work benefited from the use of artificial intelligence —specifically, a freely available one— as a collaborative tool for the refinement, articulation and organization of ideas.
While AI speeds up the communication of concepts, the framework presented in this work emerged through practical experience, engineering reasoning, reflection and continuous improvement of the underlying ideas.
Glossary
Architecture Decision Record (ADR) — A document that records significant engineering decisions and the rationale behind them.
Automation — The implementation of repeatable engineering practices through software or systems.
Continuous Improvement — The ongoing refinement of engineering knowledge, practices, processes, and tools through feedback and learning.
Engineering Activity — Any engineering work performed to design, implement, operate, maintain, investigate, improve, or support engineering systems. Engineering activities generate engineering knowledge regardless of the engineering discipline.
Engineering Artifact — A tangible representation of engineering knowledge used to communicate, preserve, govern, or operationalize engineering practices.
Engineering Completion — The state in which an engineering activity is considered fully resolved because the knowledge generated during its execution has been integrated into the Engineering Knowledge Hub, making it discoverable, reusable, and available for future engineering activities.
Engineering Input — The event, requirement, request, or condition that initiates an engineering activity. Engineering inputs vary across disciplines, but they all contribute to the Engineering Knowledge Management lifecycle.
Engineering Knowledge — The accumulated understanding, experience, and validated solutions generated through engineering activities.
Engineering Knowledge Asset — Any validated engineering knowledge that provides measurable value to the organization by supporting problem solving, decision making, standardization, automation, or continuous improvement.
Engineering Knowledge Hub — An organizational knowledge environment that integrates the mechanisms required to discover, manage, validate, connect, preserve, and reuse engineering knowledge throughout the Engineering Knowledge Management lifecycle. It may be implemented through one or multiple repositories, platforms, tools, and services.
Engineering Knowledge Management — The discipline of creating, preserving, organizing, sharing, validating, and continuously improving engineering knowledge.
Engineering Knowledge Management Framework — A structured model that integrates engineering principles, operational processes, knowledge management practices, and platform capabilities into a unified approach for creating, preserving, and continuously improving engineering knowledge.
Engineering Practice — A validated and repeatable approach for solving recurring engineering problems.
Engineering Resolution — Completing the engineering lifecycle by preserving and propagating the knowledge generated during problem resolution.
Engineering Standard — A formally accepted engineering practice adopted to ensure consistency and quality.
Engineering Tool — A software system that assists or automates engineering activities.
Guide — A document that explains concepts, procedures, or recommended approaches.
Guideline — A recommended practice that provides direction without being mandatory.
Handbook — A curated reference that consolidates engineering knowledge within a specific domain.
Knowledge Base (KB) — A structured collection of reusable engineering knowledge.
Knowledge Propagation — The process of making engineering knowledge available and reusable across an organization.
Knowledge Validation — The process of verifying that engineering knowledge is accurate, reliable, and reusable.
Operational Resolution — Restoring normal operation after an engineering event or incident.
Operationalized — The process by which engineering knowledge is transformed from documented or implicit knowledge into an integral part of engineering activities. Once operationalized, knowledge no longer exists only as information—it actively guides decisions, defines practices and processes, supports execution, and can ultimately be standardized and automated.
Organizational Capability — The collective ability of an organization to consistently solve engineering problems through reusable engineering knowledge, practices, standards, automation, and tools.
Organizational Knowledge — Engineering knowledge that has been preserved, shared, and made reusable across the organization.
Pattern Recognition — The process of identifying similarities among recurring engineering problems and their solutions.
Playbook — A coordinated collection of procedures for responding to predefined engineering scenarios.
Postmortem — A structured analysis performed after an engineering event to capture lessons learned and opportunities for improvement.
Recurring Problem — A problem that appears repeatedly during engineering activities.
Repeatable Solution — A solution that consistently resolves the same recurring problem.
Runbook — A step-by-step operational procedure for performing a specific engineering task.
Version 1.0 | First Release | July 9, 2026 Version 1.1 | Reviewed Update | July 10, 2026 Version 1.2| Structural Revision | July 11, 2026 Version 1.3 | Taxonomy Expansion | July 11, 2026 Version 1.4| Engineering Role Responsibilities Added | July 20, 2026 Version 1.5 | Conceptual Refinements and Lifecycle Clarifications | September 17, 2026